Choosing the right foundational database is one of the most critical architectural decisions that developers, technical founders, and digital creators will ever make. For more than two decades, MySQL and PostgreSQL have stood as the twin pillars of open-source relational database management systems. For years, conventional wisdom suggested a simple split: choose MySQL for fast, read-heavy web apps and traditional content management systems, or pick PostgreSQL for strict standards compliance, complex transactions, and mathematical rigor.
In 2026, that traditional dichotomy is completely obsolete. Today's applications are not merely executing basic CRUD operations against static relational tables; they are running hybrid vector embeddings for retrieval-augmented generation (RAG), querying semi-structured documents in real time, and orchestrating distributed events across edge environments. In this fast-paced landscape, PostgreSQL has pulled ahead decisively, evolving into a unified data platform. Whether you are launching a scalable SaaS, an interactive web platform, or an e-commerce ecosystem, here is why PostgreSQL should be your default choice over MySQL in 2026.
Artificial intelligence is no longer an optional add-on; it is built directly into modern search bars, recommendation engines, and customer experiences. Storing and querying vector embeddings alongside transactional relational data has become a core engineering requirement.
PostgreSQL dominates this domain through its vibrant extension ecosystem, led by pgvector. Instead of incurring high costs for standalone vector databases or enduring the synchronization overhead of dual-writing across multiple services, PostgreSQL lets you store, index, and query high-dimensional embeddings directly within your existing relational tables:
While MySQL has added basic vector functions in recent updates, its AI ecosystem remains fragmented. MySQL relies heavily on proprietary cloud plugins, whereas PostgreSQL treats vector search as a first-class citizen fully integrated into its cost-based query optimizer.
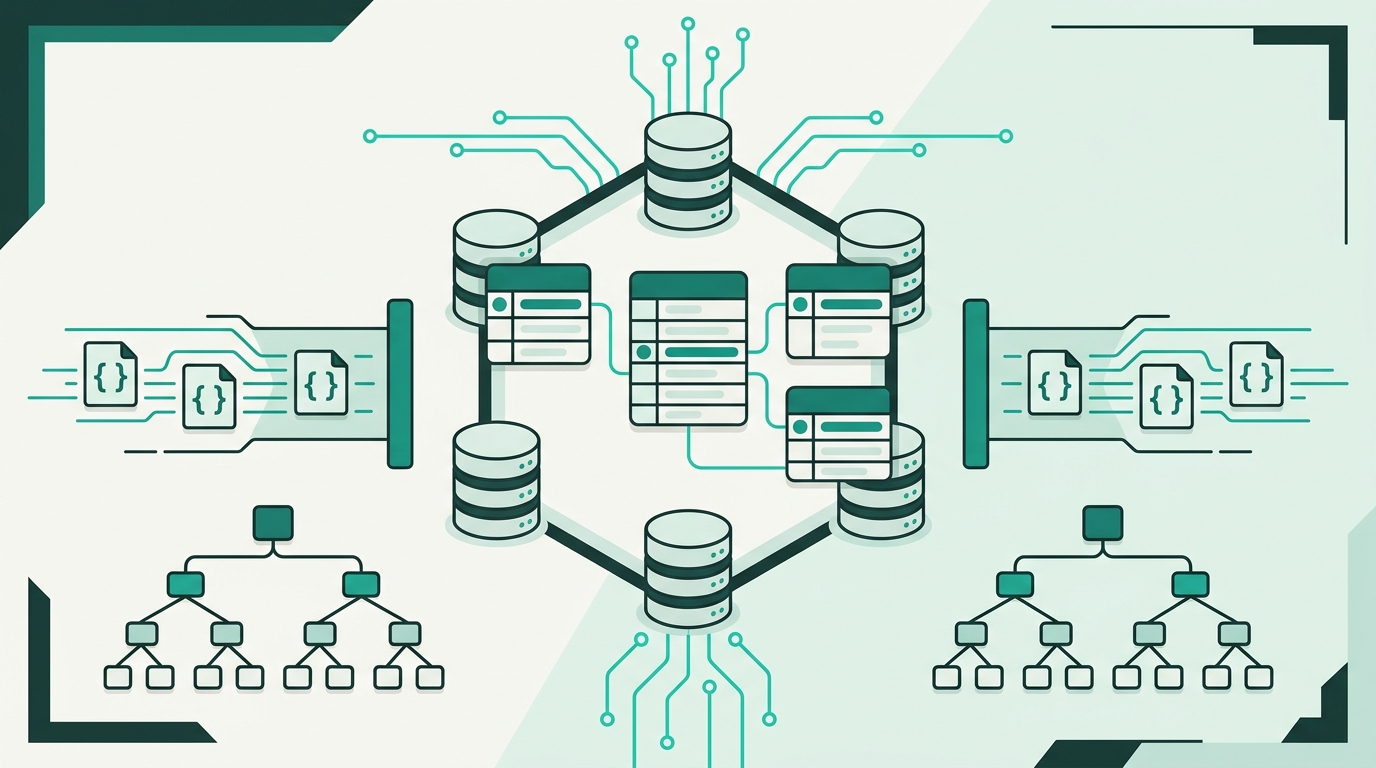
In past architectures, engineering teams frequently split their infrastructure: MySQL for relational tables and a document store like MongoDB for nested, dynamic payloads. PostgreSQL rendered this dual-database anti-pattern obsolete with its powerful JSONB data type.
Unlike standard text-based JSON, PostgreSQL's JSONB parses and stores data in a decomposed binary format. This unlocks major performance advantages:
MySQL offers a native JSON data type, but its querying semantics and indexing capabilities remain comparatively limited, often requiring virtual generated columns for indexing. When managing flexible product catalogs, creator portfolios, or headless CMS platforms—such as the custom storefronts powered by Dev Dominion for modern publishing and e-commerce—PostgreSQL's native JSONB delivers the agility of a document store alongside the safety of relational foreign keys.
Modern applications encounter unpredictable traffic spikes, asynchronous background jobs, and concurrent workflows. Under heavy throughput, how your database engine handles lock contention determines whether your application feels instantaneous or crashes under cascading timeouts.
While both databases utilize Multi-Version Concurrency Control (MVCC), PostgreSQL's concurrency execution model is remarkably refined:
SELECT ... FOR UPDATE SKIP LOCKED, allowing multiple workers to consume queue rows concurrently without lock contention.MySQL's InnoDB has made notable performance progress, but its lock manager still relies on gap locking to prevent phantom reads, which can trigger unexpected deadlock errors during concurrent batch inserts.
As datasets expand from gigabytes to terabytes, the database query optimizer becomes the primary bottleneck or accelerator. PostgreSQL's cost-based query optimizer is recognized as one of the most capable in open-source software engineering.
Key execution advantages PostgreSQL brings to demanding workloads include:
MySQL's type system is famously utilitarian. PostgreSQL, by contrast, provides an extensive array of native domain types that enforce data validation right at the storage layer:
inet and cidr types validate IP addresses and evaluate subnet masks with high efficiency.daterange and tsrange paired with GiST exclusion constraints make double-booking appointments or reservation slots physically impossible at the database level.When you are architecting a business on an all-in-one digital ecosystem like Dev Dominion, having native types and robust schema constraints ensures that your product variants, digital assets, and customer analytics stay clean and consistent over years of growth.
An honest architectural review must acknowledge where MySQL remains viable. MySQL continues to power a vast portion of the global web, particularly legacy systems and traditional content management systems.
MySQL may still be practical if:
However, for greenfield development, modern cloud architectures, API-first SaaS products, and dynamic creator platforms, MySQL's advantages have narrowed significantly, while PostgreSQL provides a modern, versatile toolkit.
If you are planning to transition from MySQL to PostgreSQL or start your next software project on solid footing in 2026, follow these practical steps:
pgloader to automate schema conversion, data casting, and index generation in a single managed pipeline.shared_buffers (typically 25% of system RAM), work_mem, and effective_cache_size to match your server resources.EXPLAIN ANALYZE to verify index usage and identify performance opportunities early.In 2026, building software is all about speed, intelligence, and architectural resilience. The era of managing three separate databases—one for relational tables, one for JSON documents, and one for vector search—is behind us. PostgreSQL has unified these capabilities into a reliable open-source foundation ready to support your application from initial prototype to global scale.
By choosing PostgreSQL today, you avoid costly technical debt, empower your stack with modern AI vector capabilities, and build on a platform designed for the future of digital software.
Leave a Comment