I woke up earlier this week to an avalanche of urgent Slack pings from panic-stricken engineering teams. DebugBear—the beloved web performance and Core Web Vitals monitoring platform that thousands of engineering blogs, SaaS publications, and technical docs rely on—had its DNS hijacked by attackers to serve malicious JavaScript. My phone practically vibrated off the nightstand.
If you're a developer or technical creator, you probably nodded knowingly when the headline broke on Search Engine Journal. You might have thought, "Glad that's a security problem, not an SEO problem."
You'd be dead wrong.
I've spent over eight years in technical SEO, untangling hreflang nightmares, auditing multi-region routing, and salvaging international organic footprints for SaaS brands. In my experience, security incidents and organic search disasters aren't separate events. They're twins. When a third-party analytics or performance script running in your blog's <head> gets hijacked at the DNS level, it doesn't just put your visitors at risk. It puts a direct hit on your Google rankings, wipes out your Core Web Vitals, and triggers automated search blacklists that can take weeks—sometimes months—to crawl out of.
Here at Dev Dominion, where we engineer and host high-performance technical publications (including this very publication, running on Dev Dominion's secured infrastructure), we immediately audited our build pipelines. But across the broader technical blogging ecosystem, the damage was already done. Let's unpack what actually happened, why your static blog isn't as bulletproof as you think, and the architectural defenses you need to implement before the next vendor goes down.
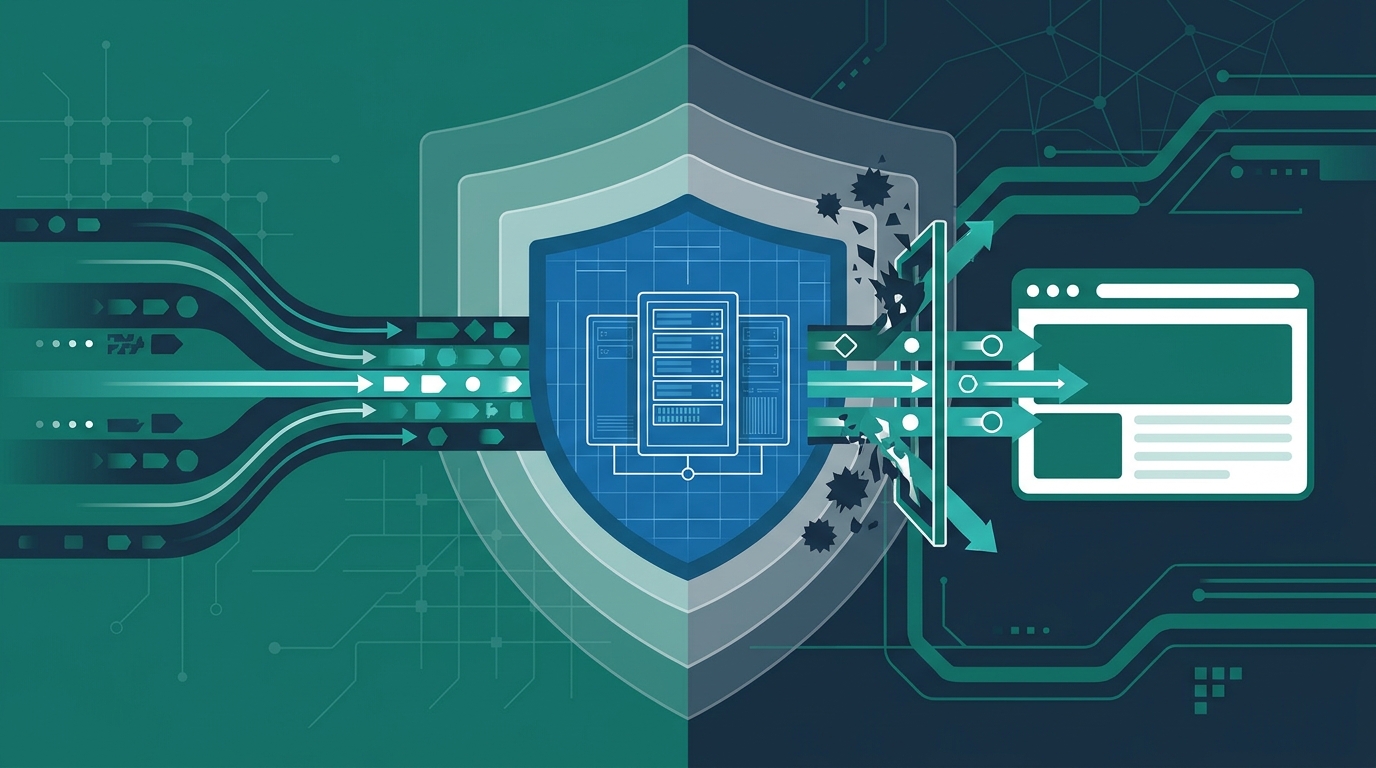
The mechanics of the DebugBear attack were ruthlessly simple. Attackers didn't breach DebugBear's application database or break into their cloud compute cluster. Instead, they compromised DNS management, repointing asset domains to malicious servers.
Think about what that means for a technical blog. You spent hours tuning your publishing stack—maybe you're running Ghost, Astro, Next.js, or Hugo. You wanted obsessive real-time insights into your Interaction to Next Paint (INP) and Largest Contentful Paint (LCP). So, like thousands of other teams, you added DebugBear's Real User Monitoring (RUM) script to your layout template:
<script src="https://cdn.debugbear.com/rum.js" async></script>You trusted the domain. Why wouldn't you? It's a top-tier performance vendor built by engineers we respect. But when the DNS switched, every visitor hitting your technical articles wasn't fetching telemetry code anymore. Their browsers were pulling down an obfuscated payload engineered to execute unauthorized redirects, siphon session tokens, or inject spam doorways into your rendered DOM. It happened silently. No alerts from your build server. No failed GitHub Actions. Just pure client-side compromise.
Most developers think Googlebot is just a dumb HTTP client that reads static HTML tags. That hasn't been true for a decade. Googlebot runs a headless Chromium rendering service with an evergreen browser engine. It executes JavaScript. It evaluates DOM mutations. It watches network requests.
When Googlebot rendered pages infected by the hijacked DNS payload, two distinct catastrophic triggers fired:
Google Safe Browsing operates independently of organic ranking algorithms, but its verdict is absolute. The moment automated scanners detect that an asset loaded by your domain distributes malware or conducts deceptive redirects, your URL enters the quarantine zone.
Chrome begins greeting your readers with a terrifying, full-screen red warning: "Deceptive site ahead." Organic Click-Through Rates (CTR) drop to zero. Literally zero. Nobody clicks past that warning screen unless they're a security researcher with a death wish.
This is where my work gets painful. For international technical blogs that publish localized content—say, an English technical deep-dive mirrored across German (/de/), Japanese (/ja/), and Spanish (/es/) subdirectories—hreflang annotations require bidirectional confirmation. Google requires that the alternate URL reciprocal-tags the canonical version.
When Googlebot encounters malicious script behavior on your primary template, it doesn't just isolate the single post. It flags the root origin. In past incidents we've remediated at Dev Dominion, we've watched multi-region indexing fall like dominos. Google drops alternate language variations from localized Search Engine Results Pages (SERPs) because it refuses to serve compromised assets to international searchers. Re-indexing twenty thousand localized technical pages across four subdirectories after a security clearance can take three to six weeks of manual index requests. The lost revenue is staggering.
Every time a WordPress security flaw surfaces, developer Twitter (or X) erupts in smug superiority: "Just switch to Hugo! Use Astro! Go headless! Static sites can't be hacked!"
Crickets now.
This attack proved what security architects have preached for years: your static markdown files might be safe from SQL injections, but your client-side runtime is as fragile as the weakest script tag you've embedded. The modern developer blog has become a Christmas tree of third-party dependencies:
Every single one of these tags represents an unauthenticated, un-sandboxed gateway into your reader's browser session. If any vendor's DNS, registrar account, or S3 bucket gets popped, your high-and-mighty static blog becomes an active malware distributor. Your static hosting on Cloudflare Pages, Vercel, or AWS S3 won't do a thing to stop it.
We can't stop vendors from having bad days or DNS registrars from getting social-engineered. But we can stop our blogging platforms from executing rogue code. Here are the four non-negotiable architectural layers we implement for technical platforms at Dev Dominion.
If your blog doesn't ship an explicit Content-Security-Policy HTTP response header, you are leaving your front door wide open. Most blogs that bother to configure CSP make the fatal mistake of using permissive wildcards:
script-src 'self' https: 'unsafe-inline'; /* THIS IS USELESS */A rule like that allows any HTTPS domain to execute scripts. When a vendor's DNS is hijacked to an attacker's HTTPS server, your browser happily runs the payload. Instead, lock down your script sources explicitly, and use cryptographic nonces generated at request time for inline snippets:
Content-Security-Policy:
  default-src 'self';
  script-src 'self' 'nonce-rAnd0m12345' https://trusted-cdn.example.com;
  object-src 'none';
  base-uri 'self';
If you run a completely static blog without a dynamic origin server to generate nonces, use SHA-256 script hashes. It takes extra work during your build step, but it eliminates arbitrary execution completely.
Subresource Integrity (SRI) allows browsers to verify that fetched resources match a cryptographic hash before executing them. It looks like this:
<script
  src="https://cdn.example.com/telemetry-v2.1.js"
  integrity="sha384-oqVuAfXRKap7fdgcCY5uykM6+R9GqQ8K/uxy9rx7HNQlGYl1kPzQho1wx4JwY8wC"
  crossorigin="anonymous">
</script>
Why didn't tech blogs have SRI on their DebugBear tags? Because SaaS vendors hate SRI. They want the freedom to push hotfixes, update features, and alter telemetry payloads dynamically without forcing you to re-deploy your site. When you load an unversioned script like rum.js, you cannot use SRI. If the hash changes, the script fails.
My advice? Push back on your vendors. Demand pinned, versioned URLs (like rum-v1.4.2.js) that allow you to generate an SRI hash in your repository. If the vendor's DNS gets hijacked and points to a malicious server, the browser checks the hash, sees a mismatch, throws a console error, and aborts execution. Your readers stay safe. Your Google rankings remain pristine.
Stop pointing your blog templates directly to third-party endpoints. Instead, route telemetry, analytics, and font requests through your own domain using edge workers (Cloudflare Workers, Fastly Compute, or Next.js middleware).
For example, you can expose a first-party endpoint like https://yourdomain.com/proxy/telemetry.js. Your edge worker fetches the upstream script, inspects cache-control headers, enforces strict timeout bounds, and sanitizes outgoing headers. More importantly, if an upstream vendor goes haywire, you can flip an edge environment variable and kill the script globally across ten million cached pages in three seconds flat. No emergency git commits. No waiting on static site builds.
Why are third-party analytics and performance scripts running on your main UI thread anyway? They don't need access to the window object. They don't need permission to manipulate your DOM or read your cookies.
Tools like Partytown allow you to run third-party scripts completely off the main thread inside a sandboxed Web Worker. The worker intercepts DOM queries through a controlled proxy. If a hijacked script tries to execute a window-level redirect or append a malicious iframe, the worker sandbox blocks it. This simultaneously protects your readers and dramatically improves your site's Interaction to Next Paint (INP) scores. That's a genuine win-win for technical SEO.
If you were caught in the blast radius of this week's DNS hijack, don't wait for Google to figure things out on its own. Every hour you delay compounds the algorithmic hit.
curl -I that the asset is no longer being requested.We spend countless hours debating the perfect static site generator, refactoring CSS to shave 12 milliseconds off First Contentful Paint, and agonizing over schema markup. Yet we casually paste third-party JavaScript snippets into our global templates without a single CSP header, without SRI verification, and without sandboxing.
The DebugBear DNS hijack is a wake-up call for every technical creator and engineering team on the web. In the modern search ecosystem, technical SEO isn't just about keywords, metadata, and clean URL slugs. It's about infrastructure resilience. If your blog's publishing stack can be turned into a malware vector because a monitoring vendor lost control of their nameservers, your organic search strategy is built on quicksand. Lock down your script tags today—before Google's crawler locks you out of the index entirely.
Leave a Comment